bundles / scipy 2.0.0.dev0+git20260907.41eeb59 / scipy / stats / _stats_py / linregress
function
scipy.stats._stats_py:linregress
source: build-install/usr/lib/python3.14/site-packages/scipy/stats/_stats_py.py:10842
Signature
def linregress(x, y, alternative = two-sided, *, axis = 0, nan_policy = propagate, keepdims = False)Summary
Calculate a linear least-squares regression for two sets of measurements.
Parameters
x, y: array_likeTwo sets of measurements. Both arrays should have the same length N.
alternative: {'two-sided', 'less', 'greater'}, optionalDefines the alternative hypothesis. Default is 'two-sided'. The following options are available:
'two-sided': the slope of the regression line is nonzero
'less': the slope of the regression line is less than zero
'greater': the slope of the regression line is greater than zero
axis: int or None, default: 0If an int, the axis of the input along which to compute the statistic. The statistic of each axis-slice (e.g. row) of the input will appear in a corresponding element of the output. If
None, the input will be raveled before computing the statistic.nan_policy: {'propagate', 'omit', 'raise'}Defines how to handle input NaNs.
propagate: if a NaN is present in the axis slice (e.g. row) along which the statistic is computed, the corresponding entry of the output will be NaN.omit: NaNs will be omitted when performing the calculation. If insufficient data remains in the axis slice along which the statistic is computed, the corresponding entry of the output will be NaN.raise: if a NaN is present, aValueErrorwill be raised.
nan_policy='raise'andnan_policy='omit'are not supported by lazy backends, andnan_policy='omit'is not compatible with MArray input. For multidimensional input,nan_policy='omit'is supported only by the NumPy backend. Instead, mask NaN values using MArray; and use the defaultnan_policy. See Notes for support information.keepdims: bool, default: FalseIf this is set to True, the axes which are reduced are left in the result as dimensions with size one. With this option, the result will broadcast correctly against the input array.
Returns
result: ``LinregressResult`` instanceThe return value is an object with the following attributes:
slope
Slope of the regression line.
intercept
Intercept of the regression line.
rvalue
The Pearson correlation coefficient. The square of
rvalueis equal to the coefficient of determination.pvalue
The p-value for a hypothesis test whose null hypothesis is that the slope is zero, using Wald Test with t-distribution of the test statistic. See
alternativeabove for alternative hypotheses.stderr
Standard error of the estimated slope (gradient), under the assumption of residual normality.
intercept_stderr
Standard error of the estimated intercept, under the assumption of residual normality.
Notes
For compatibility with older versions of SciPy, the return value acts like a namedtuple of length 5, with fields slope, intercept, rvalue, pvalue and stderr, so one can continue to write
slope, intercept, r, p, se = linregress(x, y)With that style, however, the standard error of the intercept is not available. To have access to all the computed values, including the standard error of the intercept, use the return value as an object with attributes, e.g.
result = linregress(x, y)
print(result.intercept, result.intercept_stderr)
Beginning in SciPy 1.9, np.matrix inputs (not recommended for new code) are converted to np.ndarray before the calculation is performed. In this case, the output will be a scalar or np.ndarray of appropriate shape rather than a 2D np.matrix. Similarly, while masked elements of masked arrays are ignored, the output will be a scalar or np.ndarray rather than a masked array with mask=False.
Examples
import numpy as np
import matplotlib.pyplot as plt
from scipy import stats
rng = np.random.default_rng()
✓
x = rng.random(10)
y = 1.6*x + rng.random(10)
✓
res = stats.linregress(x, y)
✓print(f"R-squared: {res.rvalue**2:.6f}")
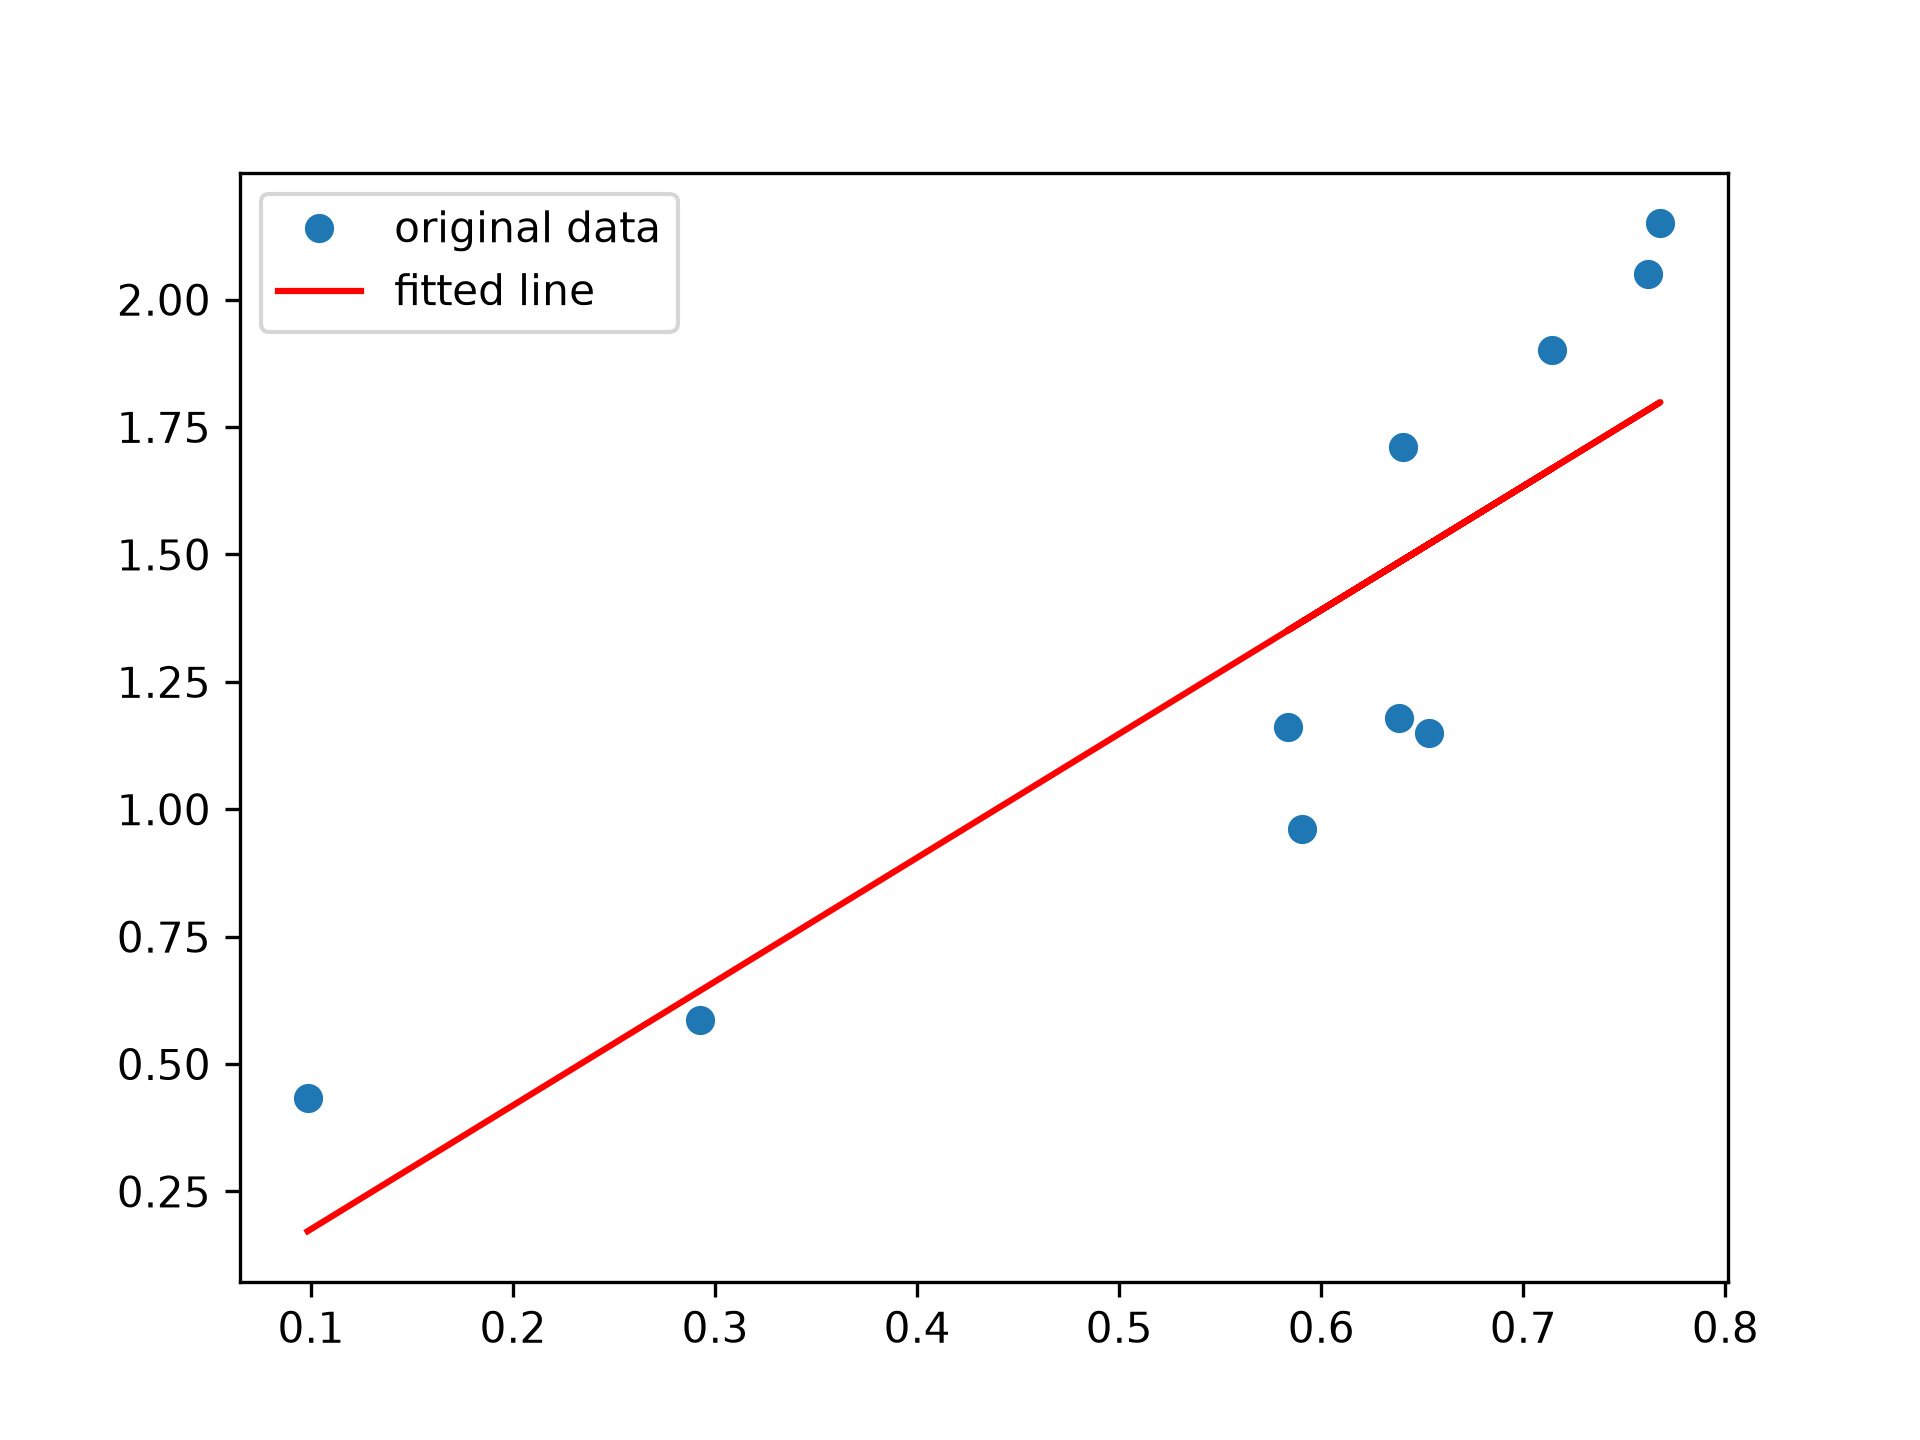
✗R-squared: 0.752698Plot the data along with the fitted line:
plt.plot(x, y, 'o', label='original data')
plt.plot(x, res.intercept + res.slope*x, 'r', label='fitted line')
plt.legend()
✗
<matplotlib.legend.Legend object at 0x7f3f60b81a90>
plt.show()
✓
from scipy.stats import t
tinv = lambda p, df: abs(t.ppf(p/2, df))
✓
ts = tinv(0.05, len(x)-2)
✓print(f"slope (95%): {res.slope:.6f} +/- {ts*res.stderr:.6f}") print(f"intercept (95%): {res.intercept:.6f}" f" +/- {ts*res.intercept_stderr:.6f}")✗
intercept (95%): -0.066974 +/- 0.691664
See also
- scipy.optimize.curve_fit
Use non-linear least squares to fit a function to data.
- scipy.optimize.leastsq
Minimize the sum of squares of a set of equations.
Aliases
scipy.stats.linregress