bundles / scipy latest / scipy / stats / _resampling / monte_carlo_test
function
scipy.stats._resampling:monte_carlo_test
source: build-install/usr/lib/python3.14/site-packages/scipy/stats/_resampling.py:794
Signature
def monte_carlo_test(data, rvs, statistic, *, vectorized = None, n_resamples = 9999, batch = None, alternative = two-sided, axis = 0)Summary
Perform a Monte Carlo hypothesis test.
Extended Summary
data contains a sample or a sequence of one or more samples. rvs specifies the distribution(s) of the sample(s) in data under the null hypothesis. The value of statistic for the given data is compared against a Monte Carlo null distribution: the value of the statistic for each of n_resamples sets of samples generated using rvs. This gives the p-value, the probability of observing such an extreme value of the test statistic under the null hypothesis.
Parameters
data: array-like or sequence of array-likeAn array or sequence of arrays of observations.
rvs: callable or tuple of callablesA callable or sequence of callables that generates random variates under the null hypothesis. Each element of
rvsmust be a callable that accepts keyword argumentsize(e.g.rvs(size=(m, n))) and returns an N-d array sample of that shape. Ifrvsis a sequence, the number of callables inrvsmust match the number of samples indata, i.e.len(rvs) == len(data). Ifrvsis a single callable,datais treated as a single sample.statistic: callableStatistic for which the p-value of the hypothesis test is to be calculated.
statisticmust be a callable that accepts a sample (e.g.statistic(sample)) orlen(rvs)separate samples (e.g.statistic(samples1, sample2)ifrvscontains two callables anddatacontains two samples) and returns the resulting statistic. Ifvectorizedis setTrue,statisticmust also accept a keyword argumentaxisand be vectorized to compute the statistic along the providedaxisof the samples indata.vectorized: bool, optionalIf
vectorizedis setFalse,statisticwill not be passed keyword argumentaxisand is expected to calculate the statistic only for 1D samples. IfTrue,statisticwill be passed keyword argumentaxisand is expected to calculate the statistic alongaxiswhen passed ND sample arrays. IfNone(default),vectorizedwill be setTrueifaxisis a parameter ofstatistic. Use of a vectorized statistic typically reduces computation time.n_resamples: int, default: 9999Number of samples drawn from each of the callables of
rvs. Equivalently, the number statistic values under the null hypothesis used as the Monte Carlo null distribution.batch: int, optionalThe number of Monte Carlo samples to process in each call to
statistic. Memory usage is O(batch*sample.size[axis]). Default isNone, in which casebatchequalsn_resamples.alternative: {'two-sided', 'less', 'greater'}The alternative hypothesis for which the p-value is calculated. For each alternative, the p-value is defined as follows.
'greater'the percentage of the null distribution that is greater than or equal to the observed value of the test statistic.'less'the percentage of the null distribution that is less than or equal to the observed value of the test statistic.'two-sided'twice the smaller of the p-values above.
axis: int, default: 0The axis of
data(or each sample withindata) over which to calculate the statistic.
Returns
res: MonteCarloTestResultAn object with attributes:
statistic
The test statistic of the observed
data.pvalue
The p-value for the given alternative.
null_distribution
The values of the test statistic generated under the null hypothesis.
: .. warning::The p-value is calculated by counting the elements of the null distribution that are as extreme or more extreme than the observed value of the statistic. Due to the use of finite precision arithmetic, some statistic functions return numerically distinct values when the theoretical values would be exactly equal. In some cases, this could lead to a large error in the calculated p-value. monte_carlo_test guards against this by considering elements in the null distribution that are "close" (within a relative tolerance of 100 times the floating point epsilon of inexact dtypes) to the observed value of the test statistic as equal to the observed value of the test statistic. However, the user is advised to inspect the null distribution to assess whether this method of comparison is appropriate, and if not, calculate the p-value manually.
Examples
Suppose we wish to test whether a small sample has been drawn from a normal distribution. We decide that we will use the skew of the sample as a test statistic, and we will consider a p-value of 0.05 to be statistically significant.import numpy as np from scipy import stats def statistic(x, axis): return stats.skew(x, axis)✓
rng = np.random.default_rng()
x = stats.skewnorm.rvs(a=1, size=50, random_state=rng)
✓
statistic(x, axis=0)
✗np.float64(-0.2482360941005758)To determine the probability of observing such an extreme value of the skewness by chance if the sample were drawn from the normal distribution, we can perform a Monte Carlo hypothesis test. The test will draw many samples at random from their normal distribution, calculate the skewness of each sample, and compare our original skewness against this distribution to determine an approximate p-value.
from scipy.stats import monte_carlo_test
rvs = lambda size: stats.norm.rvs(size=size, random_state=rng)
res = monte_carlo_test(x, rvs, statistic, vectorized=True)
✓
print(res.statistic)
print(res.pvalue)
✗
0.43The probability of obtaining a test statistic less than or equal to the observed value under the null hypothesis is ~70%. This is greater than our chosen threshold of 5%, so we cannot consider this to be significant evidence against the null hypothesis. Note that this p-value essentially matches that of `scipy.stats.skewtest`, which relies on an asymptotic distribution of a test statistic based on the sample skewness.
stats.skewtest(x).pvalue
✗np.float64(0.4289652161458558)This asymptotic approximation is not valid for small sample sizes, but `monte_carlo_test` can be used with samples of any size.
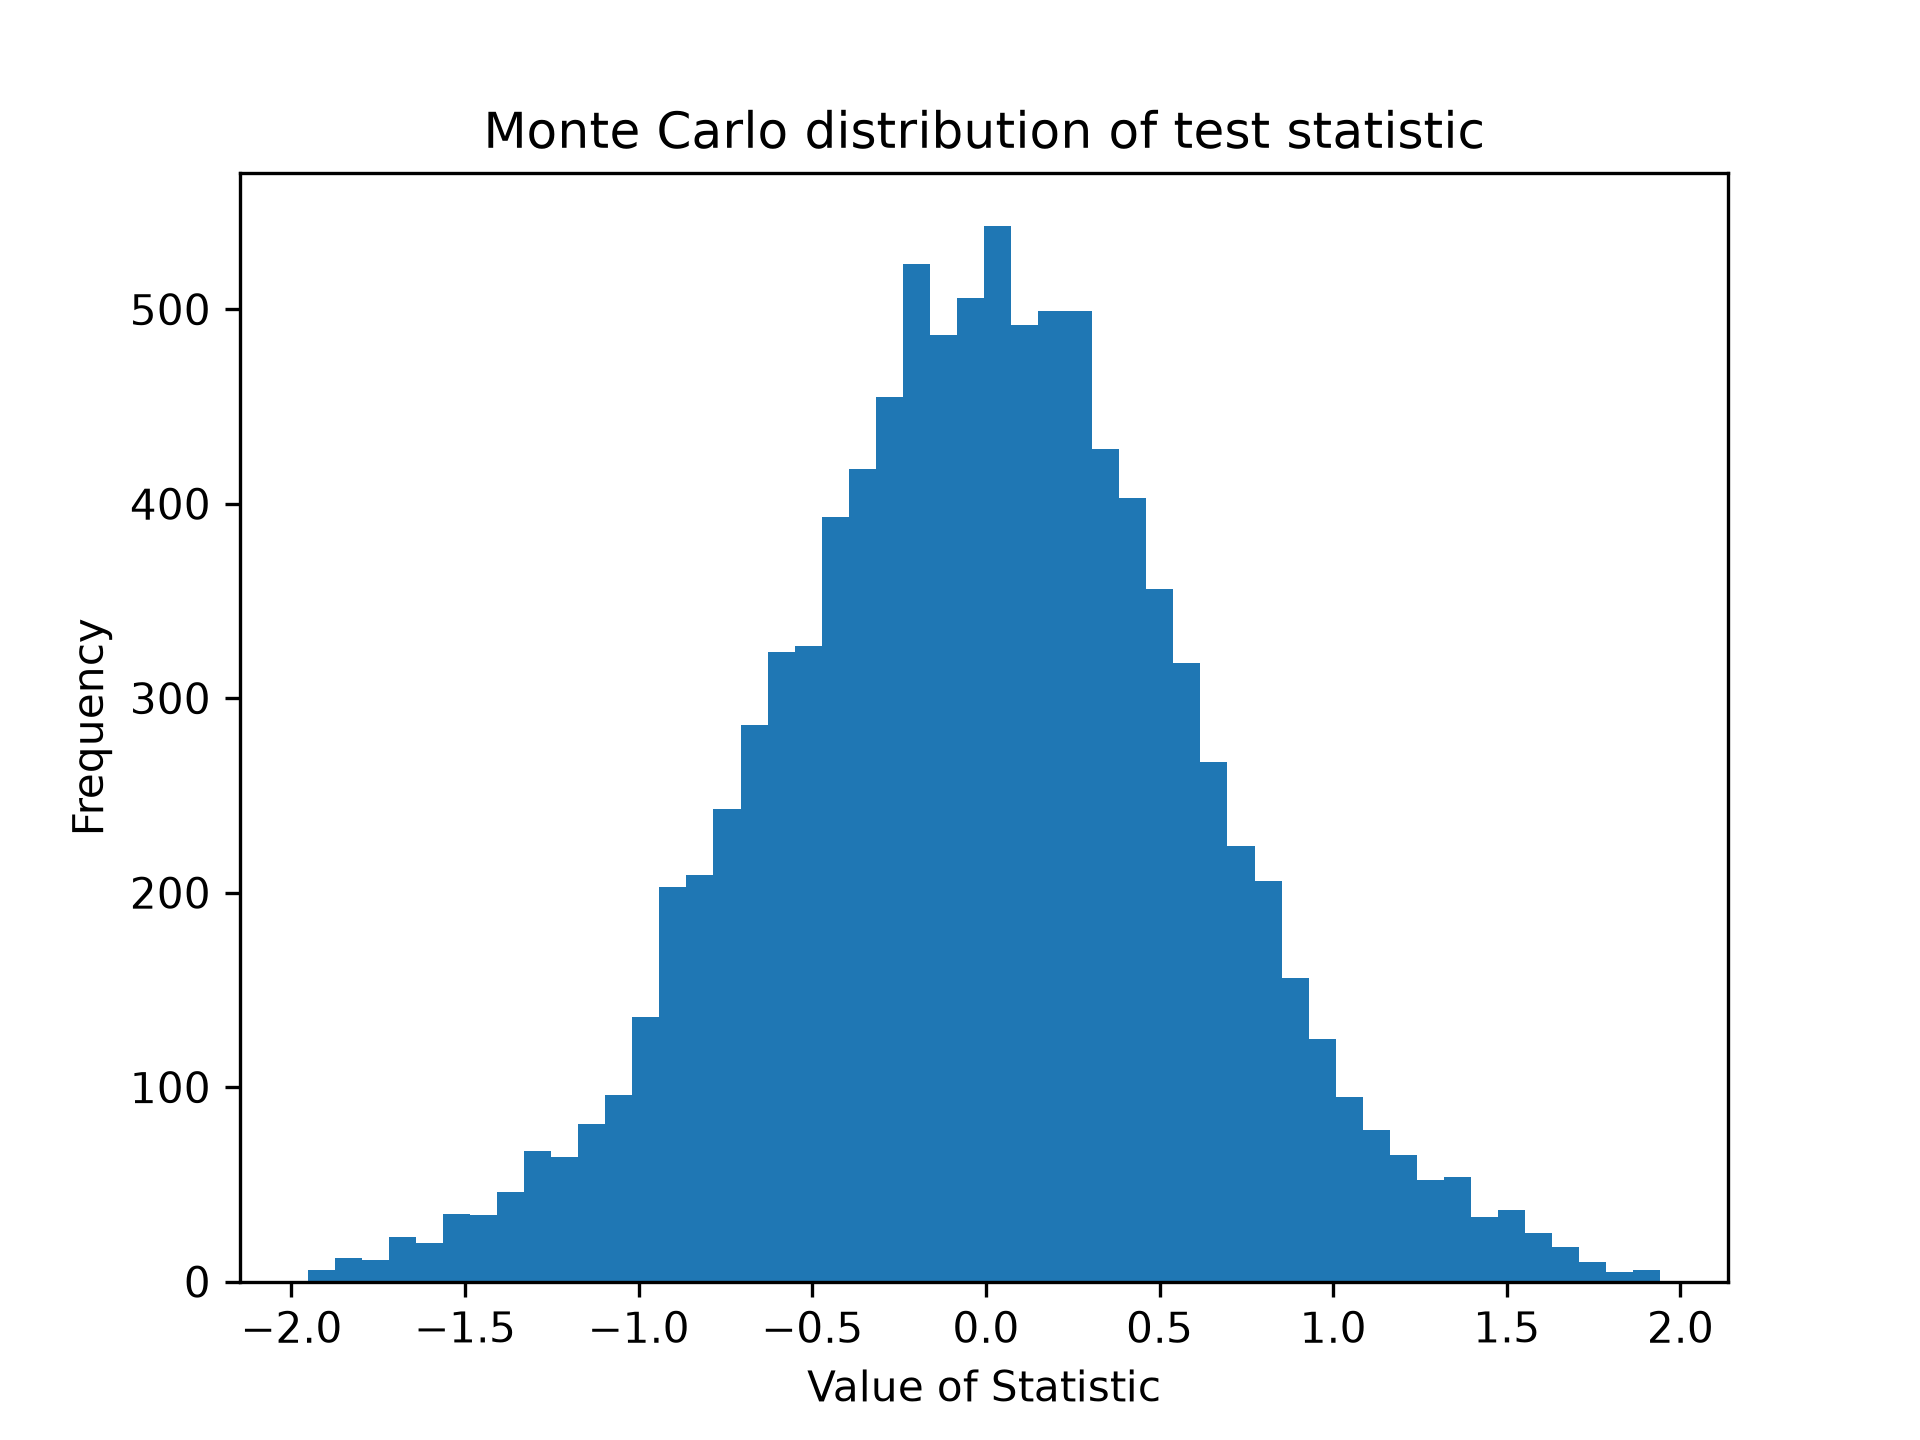
x = stats.skewnorm.rvs(a=1, size=7, random_state=rng)
res = monte_carlo_test(x, rvs, statistic, vectorized=True)
✓
import matplotlib.pyplot as plt
fig, ax = plt.subplots()
✓
ax.hist(res.null_distribution, bins=50)
ax.set_title("Monte Carlo distribution of test statistic")
ax.set_xlabel("Value of Statistic")
ax.set_ylabel("Frequency")
✗
Text(0, 0.5, 'Frequency')
plt.show()
✓
Aliases
scipy.stats.monte_carlo_test
Referenced by
This package
- release:1.10.0-notes
- release:1.11.0-notes
- release:1.13.0-notes
- release:1.14.0-notes
- release:1.9.0-notes
- scipy.stats._correlation:spearmanrho
- scipy.stats._resampling:MonteCarloTestResult
- scipy.stats._stats_py:fisher_exact
- scipy.stats._stats_py:pearsonr
- scipy.stats._stats_py:ttest_ind
- scipy.stats.contingency:chi2_contingency
- scipy.stats._morestats:anderson